AI Game Demo Debt: The $1,000-a-Day Token Cost Trap

Key Takeaways
- •The Economics of Runtime AI in Game Loops
- •The Public Demo Vulnerability
- •Architectural Safeguards for AI-Powered Games
Building a game demo has historically carried fixed, front-loaded costs. You build your vertical slice, package your client binaries, upload the build to Steam, and let Valve's content delivery network foot the bandwidth bill. Once the build is published, having ten players or ten thousand players test your game slice doesn't drastically change your studio's operational balance sheet.
However, that traditional indie economics model collapses the moment your game architecture relies on runtime cloud large language model (LLM) calls.
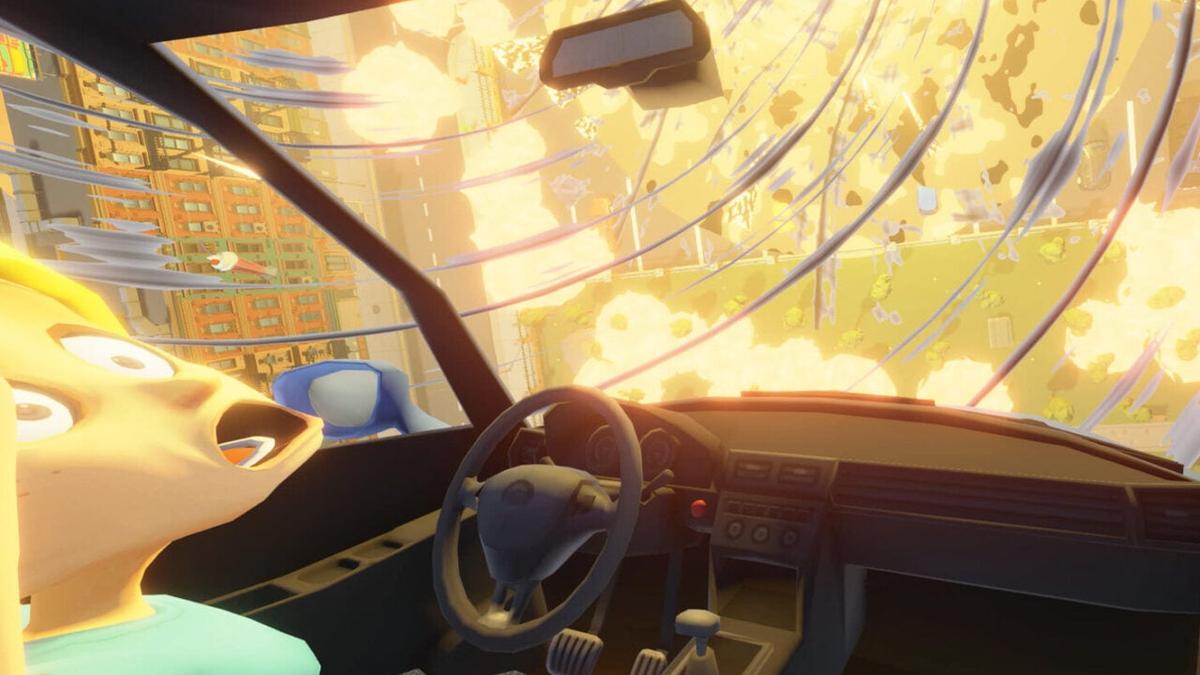
As reported by Kotaku, the developers behind the upcoming simulation title Teach My Little Sister How To Drive found this out the hard way. Aiming for release next year, the team released a playable Steam demo built around dynamic, AI-driven interactions. The result? A massive hit in user engagement, accompanied by an existential financial emergency: the demo began running up $1,000 a day in token usage expenses, rapidly sending the developers into debt simply to keep their free vertical slice online.
As engineers and technical directors, this is a wake-up call. We are watching the intersection of dynamic generative systems and real-world infrastructure bills collide in real time.
The Economics of Runtime AI in Game Loops
In conventional game loops, interactive companion non-player characters (NPCs) rely on finite-state machines (FSMs), behaviour trees, or utility AI systems. These operate entirely within client memory and hardware cycles. Whether an NPC barks ten dialogue lines or ten thousand over a play session, the marginal cost to the studio is exactly zero dollars.
When an indie team swaps hard-coded dialogue trees for third-party cloud inference endpoints, the economic architecture shifts completely from fixed development cost to variable operational expense (OpEx).
Consider the math behind a reactive companion in a driving simulator. A single dialogue round-trip does not simply process the player's immediate speech or text prompt. To maintain immersion and persona, an LLM pipeline must pass:
- System Prompts: Behavioral guidelines, safety boundaries, character quirks, and emotional states.
- Contextual History: The sliding window of recent conversation turns and events.
- World State Payloads: Vehicle speed, road hazards, navigation coordinates, collision logs, and traffic conditions.
A single interaction can easily burn between 1,000 and 2,500 tokens across prompt and completion buffers. If an engaged player chats with their digital sibling every ten seconds during a 20-minute demo run, that single session can generate over 150,000 tokens. Multiply that by several hundred or thousands of concurrent Steam demo players, and an indie team's monthly cloud bill turns into a five-figure nightmare in less than forty-eight hours.
The Public Demo Vulnerability
Demos on Steam are open to the entire world. Unlike a closed playtest where developers can distribute a limited pool of unique API authentication tokens or track user IDs against a vetted whitelist, an open Steam demo invites unrestrained stress-testing.
Furthermore, public players are naturally adversarial. When players encounter an AI-driven NPC, their immediate instinct is to probe boundaries, test edge cases, trigger hallucination loops, and feed complex paragraphs of text to see how the character reacts.
Without strict architectural guardrails, an indie studio offering a free demo is effectively running an unmetered, open public web service paid entirely out of their personal savings.
Architectural Safeguards for AI-Powered Games
If your title requires natural language processing, dynamic companion dialog, or generative narrative responses, you cannot expose naked cloud API routes directly to player interactions. Here are the core engineering strategies every developer must evaluate before deploying runtime AI.
1. Hybrid Client-Side Inference (SLMs)
The industry standard is quickly moving toward local small language models (SLMs). Running optimized quantized models directly on the user's local hardware offloads token execution to their local graphics card or neural processing unit.
- Advantage: Predictable infrastructure costs of zero dollars per token.
- Constraint: Requires strict hardware baselines and increases client download sizes.
For titles where minimum system specs allow it, bundling a compact, highly specialized local model eliminates API runaways completely.
2. Semantic Response Caching
Human players often ask predictable variations of the same situational queries. If your driving simulator's passenger is asked "Are we there yet?" or "Watch out for that car!", your backend should not send that string to an expensive frontier model every single time.
By deploying an embedding-based semantic vector cache at your API gateway, your service can check incoming input against pre-calculated responses. If the cosine similarity matches an existing safe response, return the cached completion instantly at near-zero compute cost.
3. Hard Per-Session Token Quotas
Free demos cannot afford unlimited live chat. Game designers must weave computational limits directly into narrative gameplay design:
- Give the in-game character an explicit communication stamina or cell phone battery mechanic.
- Restrict conversations to specific milestone triggers rather than continuous background audio streaming.
- Hard-cap demo sessions to a fixed token budget per verified Steam ID.
Once a player hits their demo quota, the character can smoothly transition to classic pre-scripted dialogue nodes.
Key Takeaways for Indie Studios
The situation reported with Teach My Little Sister How To Drive is a cautionary milestone for modern development. As developers, our passion for creating breakthrough emergent experiences often blinds us to backend infrastructure realities.
- Treat Cloud AI Like a Live-Service Backend: Even if your game is fundamentally a single-player experience, calling external inference engines turns it into a live-service game requiring strict server-side cost modeling.
- Gate Your Free Demos: Never offer unlimited generative features in an unmetered, free-to-play vertical slice.
- Design Fallbacks Early: If your backend cloud service experiences high latency, API timeouts, or exceeds its daily financial allowance, your game client must fail over gracefully to traditional rule-based dialogue without crashing or breaking immersion.
Generative tech presents exciting creative opportunities for systemic, reactive virtual worlds. But as this cautionary tale shows, managing your token economics is just as critical to shipping your project as managing frame time budgets and memory allocations.
At White Cube Studios, we translate technical architecture into shipping systems across our specialized development pillars: